Stackness

Blog

Updates, announcements, trends and explainers from Stackness

knowledge10 min read

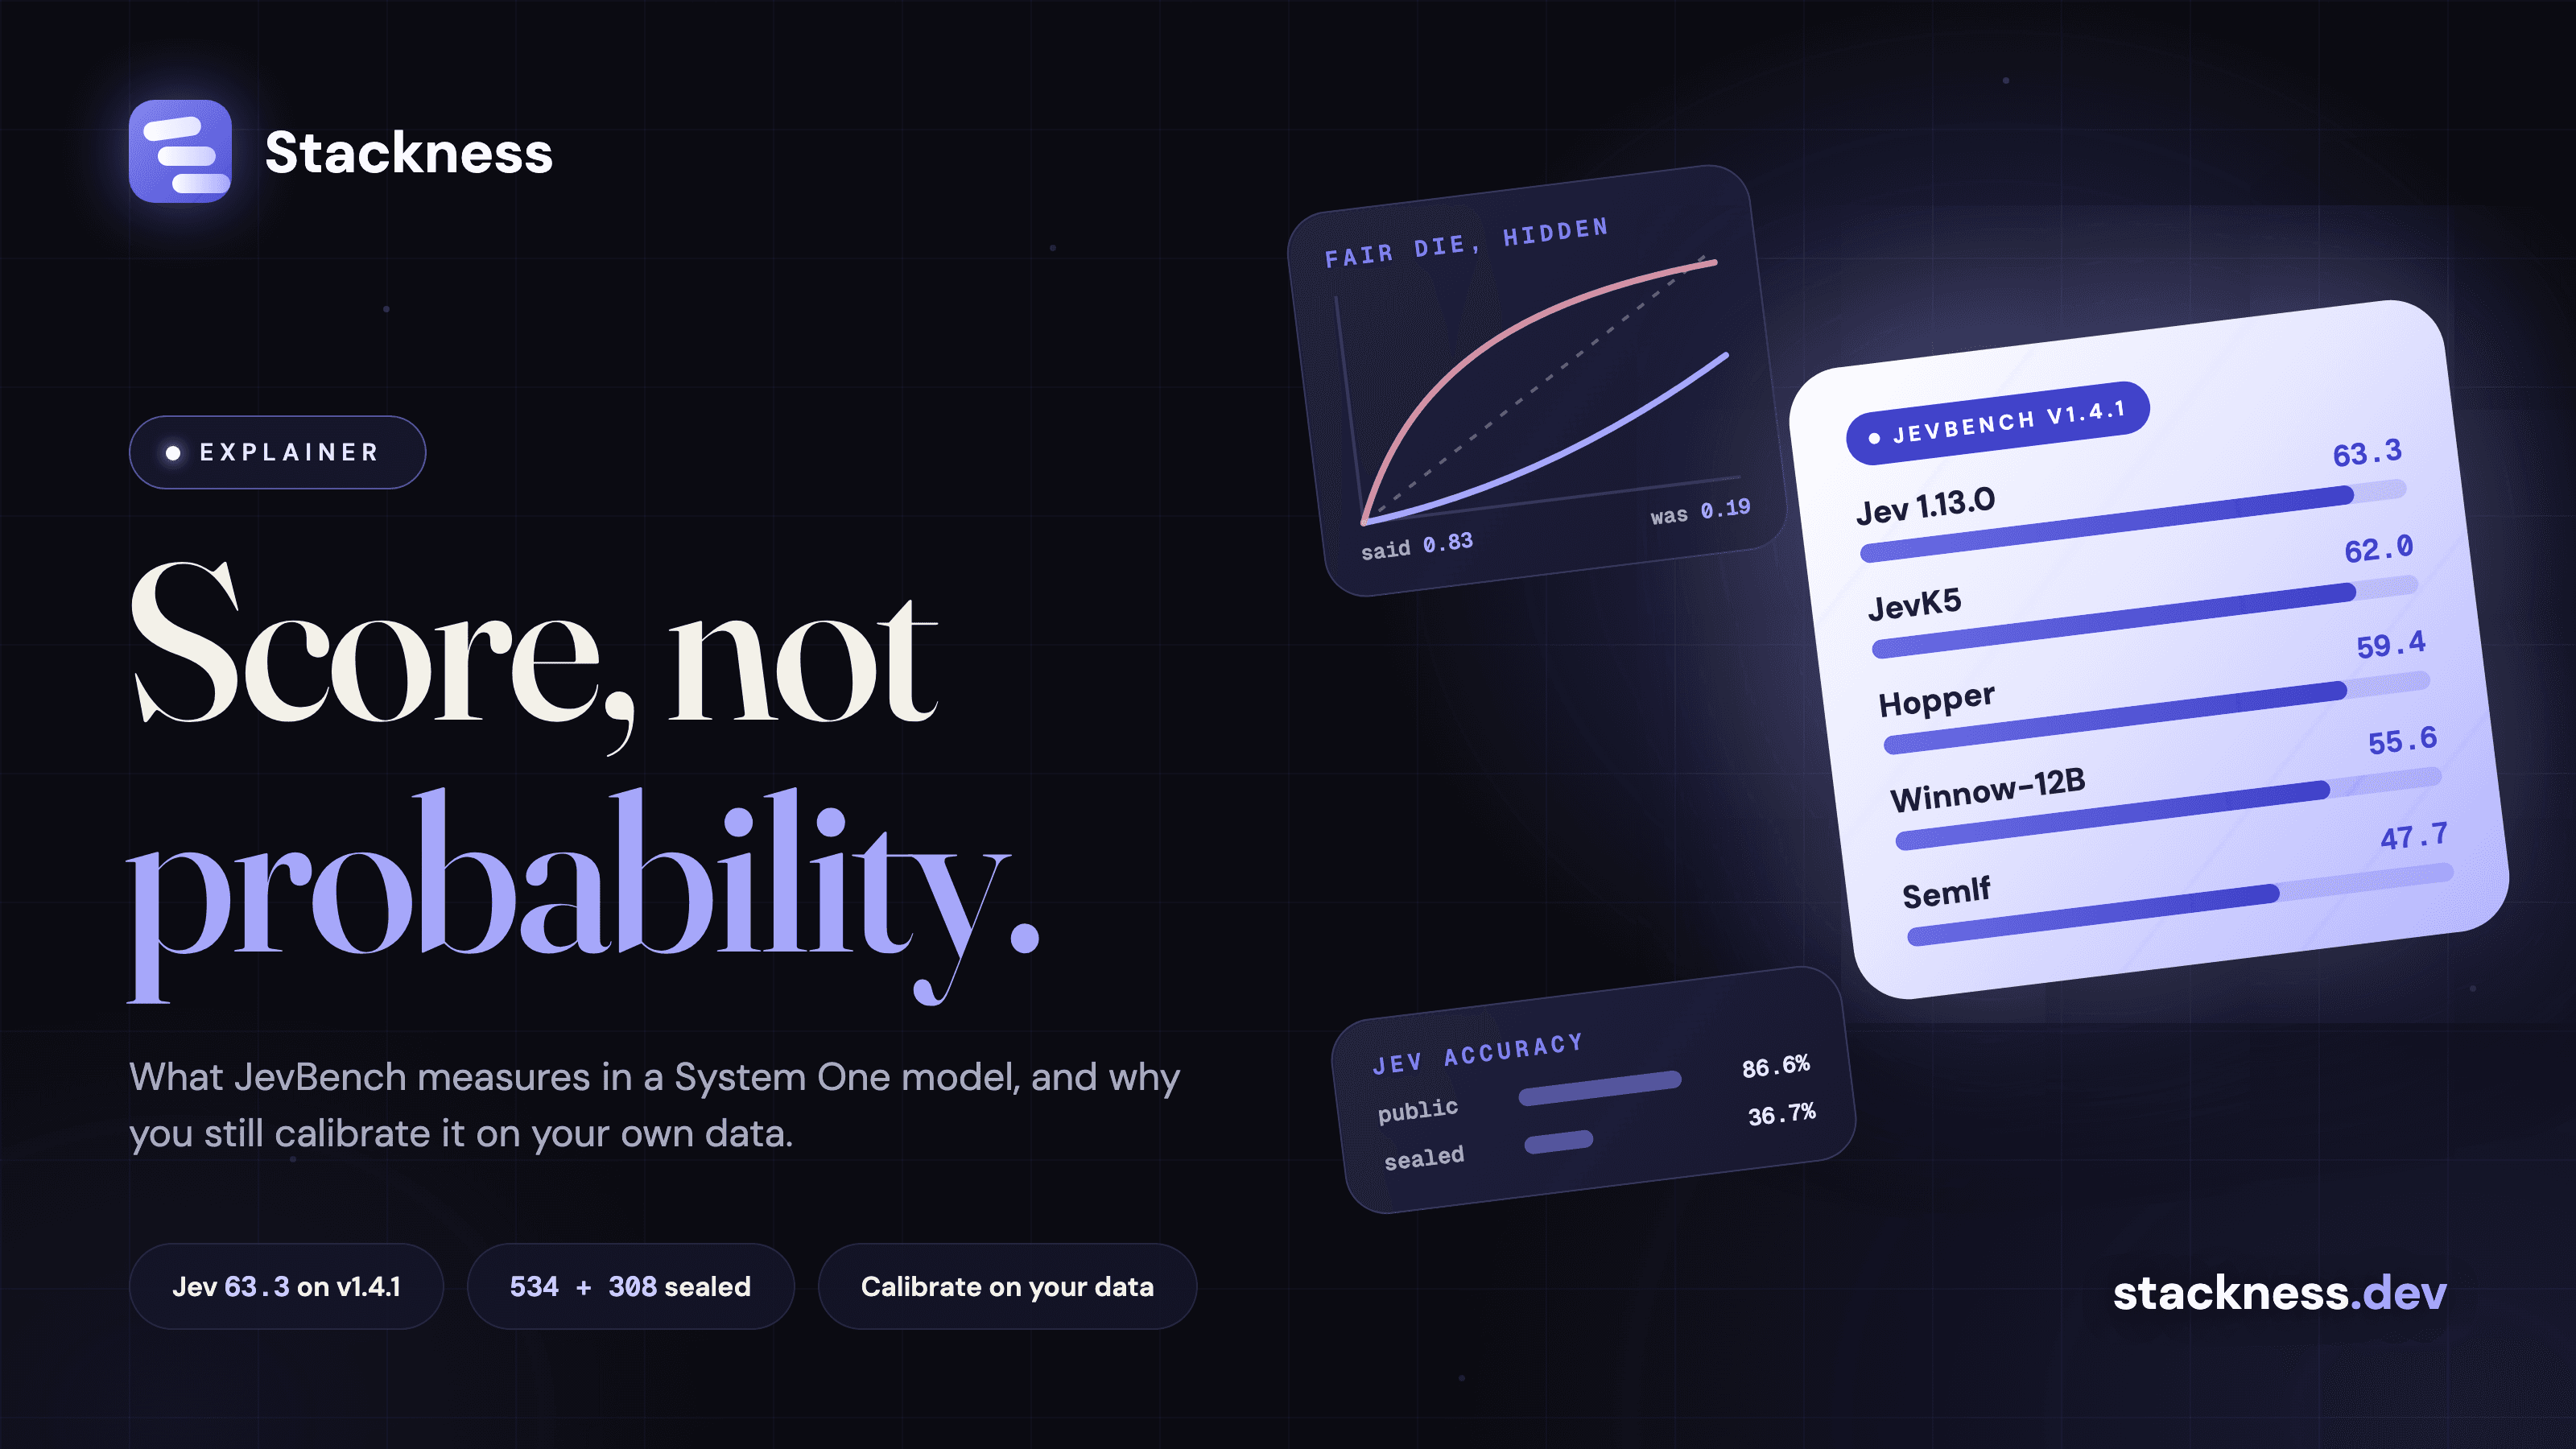
How do you benchmark a System One model? What JevBench scores, and what calibration says it cannot

JevBench scores Jev-class decision models on four axes: accuracy above chance, calibration, speed and cost per 1,000 decisions. Its v1.4.1 board puts Jev first at 63.3. A day later, a post argued that no benchmark can make these probabilities trustworthy on your data. Both are right, and this post covers what to measure yourself.

SESergei GordeichukSenior Software engineer · The master of Stackness
knowledge10 min read

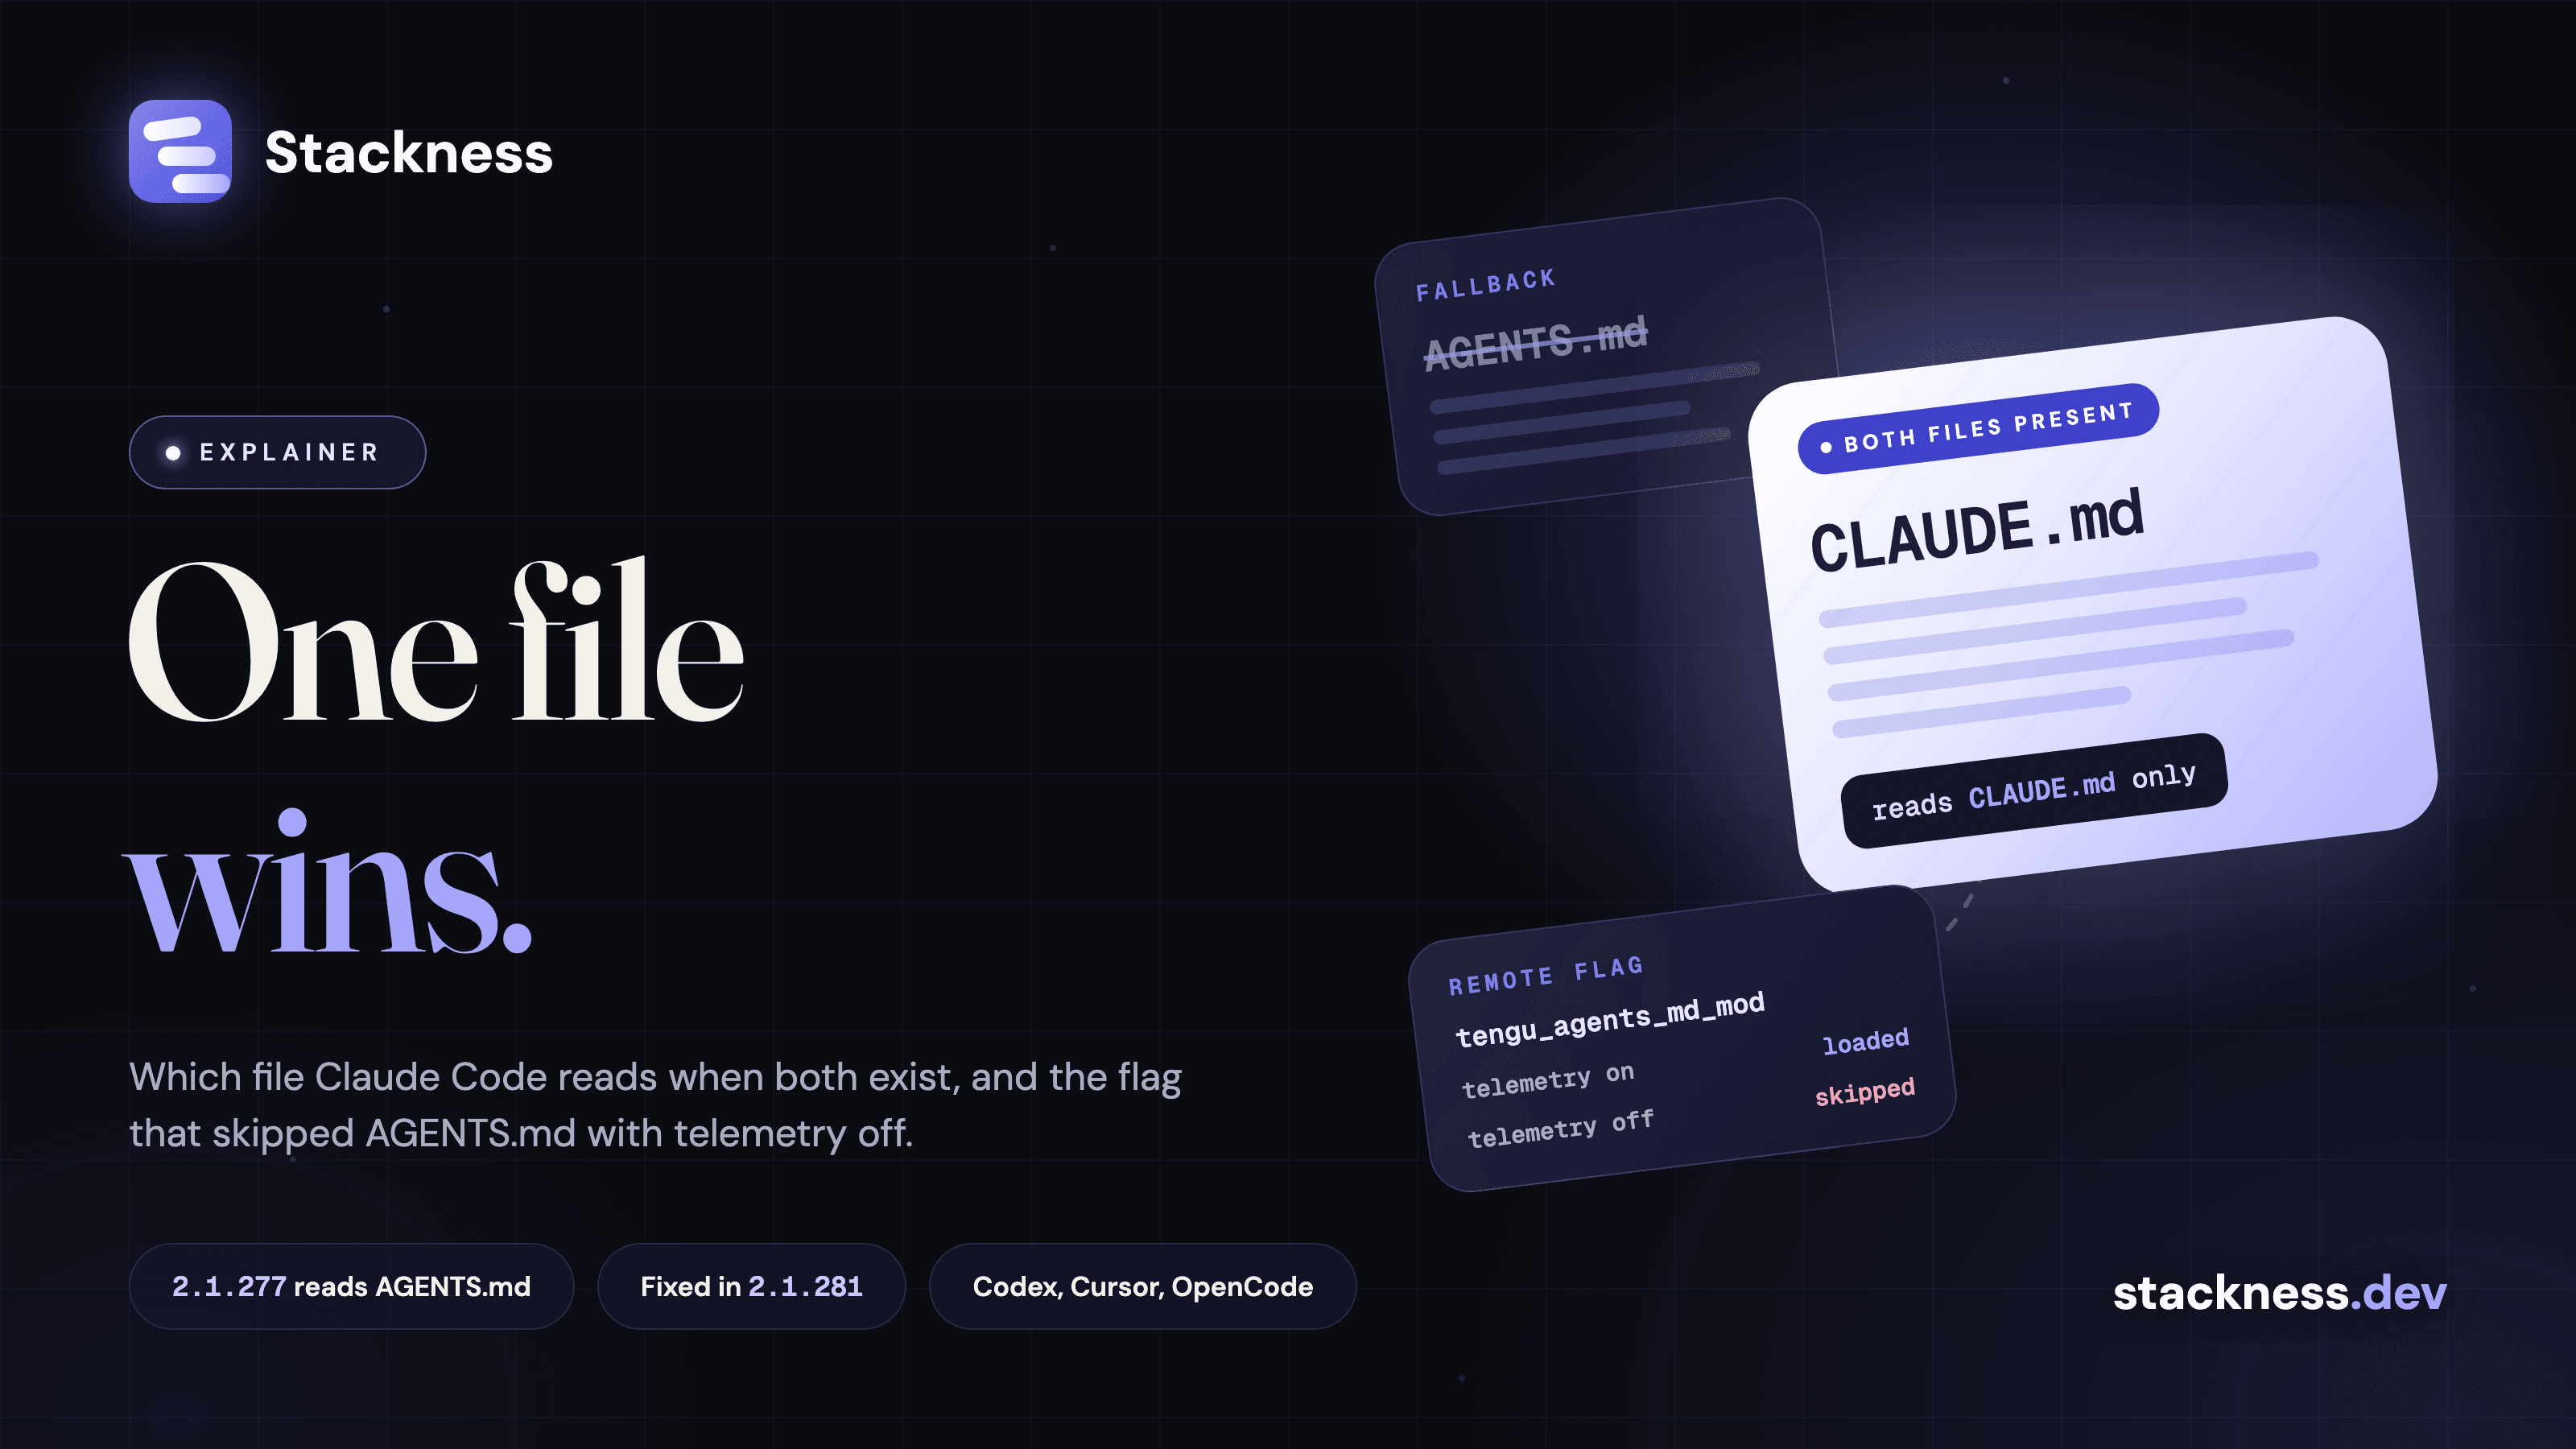
AGENTS.md vs CLAUDE.md: which file Claude Code reads, and the flag that decided it

Since 2.1.277, Claude Code reads AGENTS.md only when no CLAUDE.md or CLAUDE.local.md sits in the working directory or above it. Until 2.1.281, a remote feature flag also skipped the file without a warning for anyone with telemetry off. Here is the precedence table, how to check what loaded, and which other agents read the same file.

SESergei GordeichukSenior Software engineer · The master of Stackness
trend6 min read

August 2026 in dev stacks: agent harnesses, native TypeScript, and Postgres for everything

August is supposed to be the quiet month. Instead we got a compiler changing languages, a protocol getting audited in public, and Hacker News once again deciding that Postgres is the answer to every question. Here is what actually moved in developer stacks this month - not the product launches, but the shifts that change what you would put in a new project today.

SESergei GordeichukSenior Software engineer · The master of Stackness